Code Reviews Are Not Code Police

The Theater of Nitpicking

I’ve been doing code reviews for fifteen years, and I can tell you that most teams are doing them spectacularly wrong. They’ve turned what should be collaborative learning sessions into Byzantine rituals of nitpicking where someone inevitably argues about variable naming for forty-seven comments while completely missing the fact that the entire approach is fundamentally flawed.
Code Reviews Are Not Code Police

The worst offenders are teams that treat code reviews like some kind of quality gate where the senior engineer plays sheriff, slapping down anyone who dares to write a for-loop when they could have used a map function. I’ve watched brilliant junior developers get demoralized by reviews that read like hostile takeovers, where every line gets dissected with the enthusiasm of a pathologist examining a particularly interesting corpse.

Here’s what everyone seems to miss: code reviews aren’t about finding every possible improvement. They’re about finding problems that matter. That missing semicolon? Your linter should catch it. That variable name that could be slightly more descriptive? Probably not worth the cognitive load of a back-and-forth discussion unless it’s genuinely confusing.
Illustration for Code Reviews Are Not Code Police

What Actually Deserves Your Attention

After debugging production systems at ungodly hours, I’ve developed a pretty clear hierarchy of what matters in code reviews. Security vulnerabilities top the list, obviously. SQL injection, XSS, authentication bypasses. These are the things that will wake you up at 3 AM with your phone buzzing like an angry wasp.

Next comes logic errors and edge cases. I once watched a teammate push code that worked perfectly for positive numbers but hilariously exploded when someone passed in zero. The tests all passed because nobody thought to test the obvious edge case. These bugs make customers angry and managers nervous.

Performance issues that will actually impact users deserve attention too. Not the theoretical “this could be O(n²) instead of O(n log n)” stuff that will never matter with real-world data sizes, but the actual “you’re making 47 database calls in a loop” problems that will bring your application to its knees.

Architecture decisions that will make future development painful are worth discussing. If someone is about to add yet another parameter to a function that already has twelve parameters, that’s a conversation worth having. If they’re building something that violates the established patterns in your codebase without a compelling reason, speak up.

The Art of Useful Feedback

Good code review comments are like good debugging. They get straight to the point and explain the why, not just the what. Instead of “this is wrong,” try “this will fail when the API returns null, which happens during maintenance windows.” Instead of “use a constant,” explain “hardcoded timeouts like this caused an outage last month when the third-party service started responding slower.”

The best reviewers I’ve worked with ask questions instead of making demands. “Have you considered what happens if this times out?” opens a dialogue. “This will time out” sounds like you’re handing down commandments from the mountain. One approach teaches, the other just demonstrates that you’re smarter than the person who wrote the code.

When you suggest changes, provide examples. Don’t just say “this could be cleaner”. Show what cleaner looks like. Better yet, explain why it matters. “This approach separates concerns better” is infinitely more useful than “refactor this.”

And for the love of all that is holy, if you’re going to suggest a completely different approach, pick up the phone or walk over to their desk. Some conversations are too complex for GitHub comments, and watching someone try to explain architectural decisions through a series of increasingly frustrated comment exchanges is like watching someone try to perform surgery through a telescope.

Building a Culture That Actually Works

The teams with the best code review culture share a few common traits. First, they have clear guidelines about what matters and what doesn’t. They’ve collectively decided that arguing about tabs versus spaces wastes everyone’s time, so they automated those decisions with prettier or similar tools.

They also rotate review assignments so knowledge spreads across the team instead of creating bottlenecks where everything has to go through the one senior engineer who knows the codebase. I’ve seen too many teams where the “senior code reviewer” becomes a single point of failure, burning out from the constant context switching while everyone else learns nothing about the parts of the system they don’t directly work on.

Good teams also understand timing. If someone needs feedback on the overall approach, they share a draft early. If they just need a final check before deployment, they say so explicitly. The review for “is this the right way to solve this problem” looks very different from “does this implementation have any obvious bugs.”

Most importantly, they treat code reviews as learning opportunities for everyone involved, not just the person who wrote the code. I’ve learned some of my best tricks from reviewing other people’s solutions to problems I thought I already knew how to solve.

The Human Element

Code reviews are fundamentally human interactions, which means they’re subject to all the usual human weirdness. People have bad days, misread tone in written comments, and sometimes get defensive about code they wrote at 11 PM while fighting a production fire.

I’ve found that the best approach is to assume positive intent and be generous with context. If someone writes code that seems obviously wrong, maybe they’re working around a constraint you don’t know about. Ask about it before assuming they made a mistake.

Remember that the person reading your review comments is probably already a little nervous about having their work scrutinized. A little kindness goes a long way. “Nice solution to the caching problem” costs you nothing but can make someone’s day considerably better.

The goal isn’t perfect code. It’s code that works, is maintainable, and doesn’t introduce unnecessary risk. Everything else is just optimization, and premature optimization is still the root of all evil, even in code reviews.

What’s your take on code review culture? Have you found approaches that work particularly well, or horror stories that make you question the entire practice? I’m always curious to hear how different teams handle this particular blend of technical judgment and human psychology.

Why Your Database Is Slow (And It’s Probably Not What You Think)

Last Tuesday at 2:47 AM, our primary database decided to throw a tantrum. Response times spiked to 12 seconds. The on-call engineer’s first instinct? Add more RAM. Classic move. Except our memory utilization was sitting at 23%. The real culprit was a single query that had been running fine for eight months until someone added an innocuous WHERE clause that turned our carefully crafted index into digital confetti.

This is database performance optimization in the real world. Not the clean textbook scenarios where adding an index magically fixes everything, but the messy reality where a single character change can bring your entire application to its knees. After debugging enough of these disasters, I’ve noticed that most performance problems fall into predictable categories that have nothing to do with buying bigger hardware.

Query Plans Are Liars (But Useful Ones)

Your database’s query optimizer is basically a very sophisticated guesser. It looks at your query, examines available indexes, checks table statistics, and makes an educated guess about the fastest execution path. Sometimes it’s brilliant. Sometimes it decides that scanning 10 million rows is faster than using your perfectly crafted index because the statistics haven’t been updated since the Clinton administration.

PostgreSQL’s EXPLAIN ANALYZE became my best friend after I spent three days hunting down why a query that should return in milliseconds was taking 45 seconds. The query planner had decided that a sequential scan of our largest table was more efficient than using an index, because the table statistics showed 1,000 rows when we actually had 2.3 million. One ANALYZE command later, query time dropped to 12 milliseconds. The lesson? Trust your query planner, but verify with fresh statistics.

MySQL’s query plans can be even more mysterious. I once watched a developer add FORCE INDEX hints to every query in their application because they didn’t trust the optimizer. Six months later, those same hints were causing performance regressions because the data distribution had changed. The database wanted to use a different index, but the hints forced it down a suboptimal path. Modern optimizers are generally smarter than we are, but only when they have accurate information to work with.

Index Design Is Not About Adding More Indexes

The most expensive lesson I learned about indexing happened on a table with 47 indexes. Yes, forty-seven. Every time someone reported a slow query, the solution was to add another index. Inserts that should have taken milliseconds were taking seconds because the database was spending more time maintaining indexes than actually storing data. We dropped 39 indexes and performance improved across the board.

Composite indexes are where the real magic happens, but they’re also where most people get confused. The order of columns in a composite index matters enormously. An index on (user_id, created_date, status) can efficiently handle queries filtering on user_id alone, or user_id and created_date together, but it’s useless for queries filtering only on status. This isn’t theoretical knowledge you’ll never use. Last month I watched a team rebuild their entire indexing strategy because they had the column order backwards on their most important query.

Partial indexes are PostgreSQL’s secret weapon that nobody talks about. Instead of indexing every row in a table, you can create an index that only covers rows matching specific criteria. We had a table where 95% of the rows had status=’archived’ and only 5% were active. A partial index on WHERE status != ‘archived’ reduced the index size by 90% and made queries on active records blazingly fast. MySQL users get sad when they hear about features like this.

Connection Pooling Is Not Optional (Despite What Your Framework Says)

Database connections are expensive. Creating a new connection involves TCP handshakes, authentication, and various initialization overhead that can easily add 50-100 milliseconds to your request time. Yet I regularly see applications that create a new database connection for every request because “the framework handles it automatically.” The framework is lying to you.

PgBouncer saved our bacon during a traffic spike that would have otherwise brought down our PostgreSQL cluster. Our application was creating 500+ concurrent connections during peak hours, exhausting the database’s connection limit and causing cascading failures. PgBouncer pools those connections down to a manageable 25-50 actual database connections, with transaction-level pooling ensuring that connections are released immediately after each transaction completes.

Connection pool sizing is more art than science, but there’s a reasonable starting point. For PostgreSQL, the sweet spot is usually 2-3 connections per CPU core on the database server. Going higher often hurts performance because of context switching overhead. I’ve seen teams set their pool size to 500 connections because “more must be better” and then wonder why their 8-core database server is struggling. The database can only execute so many queries simultaneously before it starts thrashing.

Caching Strategies That Actually Work in Production

Redis is not a magical performance fairy that makes all your problems disappear. It’s a tool, and like any tool, it can be used poorly. The most common mistake I see is caching individual database rows in Redis and then making 47 separate cache calls to reconstruct a single page. Congratulations, you’ve replaced one database query with 47 network round-trips to Redis. Your performance is now worse, and you have cache invalidation problems to boot.

Application-level caching often gives you better bang for your buck than trying to cache at the database level. We implemented a simple in-memory cache for user permission lookups that reduced our database load by 60%. The cache holds the 10,000 most recently accessed user permission sets, expires entries after 5 minutes, and invalidates specific users when permissions change. Total implementation time: two hours. Performance improvement: dramatic.

Database-level query caching sounds appealing but rarely works as advertised in high-traffic applications. MySQL’s query cache was deprecated in version 8.0 because it caused more performance problems than it solved. The cache invalidation logic was too aggressive, invalidating all cached queries for a table when any row in that table changed. Your e-commerce site’s product catalog query gets cached, then someone updates a product description, and suddenly every cached query for the products table is invalidated. It’s more overhead than benefit in most real-world scenarios.

Monitoring What Actually Matters

Most database monitoring focuses on the wrong metrics. CPU usage and memory consumption are lagging indicators that tell you something is wrong but not what. Query execution time, connection pool utilization, and slow query logs tell you where to look for problems. I learned this the hard way when our monitoring showed perfect resource utilization while users complained about slow page loads. The issue was connection pool exhaustion causing 2-second waits for available connections.

PostgreSQL’s pg_stat_statements extension is criminally underutilized. It tracks execution statistics for all SQL statements, showing you exactly which queries are eating the most resources over time. You’ll be shocked at what you find. That innocent-looking query that developers swear “only runs occasionally” might actually be your top resource consumer. We discovered that a background job was accidentally running a full table scan every 30 seconds instead of every 30 minutes because of a cron configuration error.

Database performance optimization isn’t about following a checklist of best practices. It’s about understanding your specific workload, measuring the right things, and making targeted improvements based on evidence rather than assumptions. The next time your database is slow, resist the urge to throw hardware at the problem. Fire up your query analyzer and start digging. You might be surprised what you find lurking in those execution plans.

The Five Security Holes Everyone Ignores Until They Don’t

Supply Chain Attacks Are Your New Reality Check

Remember when we thought the worst thing that could happen was SQL injection? Those were simpler times. Today’s threat landscape looks like a game of three-dimensional chess where half the pieces are invisible and the other half are actively trying to poison your dependencies. Supply chain attacks have moved from theoretical concerns to weekly headlines, and honestly, most of us are still catching up.

The Five Security Holes Everyone Ignores Until They Don't
The Five Security Holes Everyone Ignores Until They Don’t

The SolarWinds breach wasn’t a one-off. It was a trailer for what’s coming. When attackers realized they could compromise thousands of organizations by poisoning a single widely-used library, they didn’t just stumble onto a new technique. They found the weak spot in modern software development: our complete dependence on open source packages. Your average Node.js project pulls in more dependencies than a small city’s worth of software. Each one is a potential entry point.

What makes this really sneaky is how we’ve built our entire ecosystem on trust. We download packages from npm, PyPI, and RubyGems like we’re picking up groceries. But when did you last audit the source code of that innocent utility library? The one with 50 million weekly downloads and a maintainer who disappeared in 2019? Right, never.

Illustration for The Five Security Holes Everyone Ignores Until They Don't
Illustration for The Five Security Holes Everyone Ignores Until They Don’t

Container Escape Vulnerabilities That Keep Me Up at Night

Docker changed everything, and I mean that in both the best and worst possible ways. We’ve containerized our applications like it’s a religion, convinced that isolation equals security. Plot twist: container boundaries are more like suggestions than actual walls. This gets especially fun when you’re running privileged containers or mounting host directories with zero regard for the principle of least privilege.

The really entertaining part is how we’ve normalized running containers with capabilities that would make a 2005 sysadmin break out in hives. Need access to the Docker socket? Sure, mount it as a volume. What could go wrong? Everything, as it turns out. A compromised container with access to the Docker daemon means game over. It’s like handing someone your house keys and acting shocked when they redecorate.

Here’s what keeps security researchers awake: the creative ways containers escape their supposed sandboxes. Kernel exploits, shared namespaces, and my personal favorite, the classic “oops, I’m running as root” scenario. The number of production environments I’ve seen where containers run with unnecessary elevated privileges is both hilarious and terrifying. We’ve apparently decided that defense in depth means having really good coffee while our infrastructure burns down.

Secrets Management (Or the Lack Thereof)

Let’s talk about the elephant in the room: how we handle secrets. By “handle,” I mean “scatter them around our codebase like confetti at a very dangerous party.” Environment variables seemed like such a clean solution until someone realized they’re visible in process lists, container manifests, and basically anywhere you look if you know where to squint.

I’ve lost count of how many times I’ve seen database credentials hardcoded in config files, API keys committed to public repos, or sensitive tokens passed as command-line arguments. It makes me question our collective judgment. GitHub’s secret scanning has prevented countless breaches, but it’s basically digital archaeology at this point. We’re excavating decades of poor decisions one leaked AWS key at a time.

Modern secret management solutions like HashiCorp Vault, AWS Secrets Manager, and Azure Key Vault exist, but adoption feels glacial. The friction between “doing it right” and “shipping by Friday” usually results in another plaintext password making its way into a Docker environment file. It’s the security equivalent of knowing you should exercise but ordering pizza instead because convenience always wins short-term.

API Security in a GraphQL World

REST APIs were complicated enough when we only had to worry about proper authentication and rate limiting. Then GraphQL showed up and decided to make things interesting. Don’t get me wrong, GraphQL is brilliant for frontend development. It’s also a security professional’s fever dream because it turns every client into a potential query optimizer with malicious intent.

The flexibility that makes GraphQL powerful also makes it dangerous. Clients can craft deeply nested queries that bring your backend to its knees faster than a poorly optimized database join. Traditional API security tools weren’t designed for this level of query complexity, which means most organizations are flying blind when it comes to understanding what their GraphQL endpoints actually do under load.

Rate limiting becomes an exercise in creative mathematics when a single request can trigger hundreds of database queries. Authentication and authorization get weird when your schema exposes relationships that cross security boundaries. And don’t get me started on introspection being enabled in production. It’s like leaving your API documentation on the front porch with a note that says “hack me.”

The Infrastructure-as-Code Explosion Radius

Terraform and CloudFormation were supposed to make infrastructure management more reliable and secure. Mission accomplished on the reliability front, but security is messier. When you can spin up entire AWS environments with a single command, you can also misconfigure them with unprecedented efficiency and scale.

The blast radius of a mistake has grown exponentially. One poorly configured Terraform module can create security groups that expose databases to the internet, IAM roles with excessive permissions, or storage buckets that leak customer data. The democratization of infrastructure deployment is fantastic until someone with limited security knowledge starts provisioning production resources at 2 AM.

What’s particularly entertaining is watching organizations treat infrastructure code with the same casual attitude they once reserved for application code. Code reviews that focus on functionality but ignore security implications. Modules shared across teams without considering the cumulative risk. And my personal favorite: copy-pasting Terraform snippets from Stack Overflow without understanding what they actually do.

Security in modern development stacks isn’t just about preventing the obvious attacks anymore. It’s about understanding how our tools, dependencies, and deployment processes connect and interact. The solutions exist, but they require the kind of systematic thinking that doesn’t always align with shipping quarterly features. What security blind spots are you discovering in your stack? I’d love to hear about the creative ways things are breaking in your environment.

Why Your Cloud Bill Is a Code Smell (And How to Fix It Without Breaking Everything)

The $47,000 Lambda That Taught Me Everything

Last month I watched a perfectly reasonable engineer accidentally rack up a $47,000 AWS Lambda bill in three days. The function was processing images, nothing exotic, but somewhere between the excitement of serverless and the pressure of shipping, they’d managed to create what I can only describe as a distributed money incinerator. The function was calling itself recursively through S3 events, each invocation spawning dozens more, like some kind of digital hydra with an American Express card.

Why Your Cloud Bill Is a Code Smell (And How to Fix It Without Breaking Everything)

This wasn’t stupidity. This was what happens when smart people optimize for the wrong metrics. The engineer had built something that worked beautifully in staging, scaled automatically, and met every performance requirement. It just happened to treat the AWS billing department like a slot machine jackpot. After we fixed it (a five-line change involving a simple lock mechanism), I realized something: your cloud bill isn’t just a business expense. It’s a direct reflection of how well you understand distributed systems.

High cloud costs aren’t usually about AWS being expensive. They’re about code that doesn’t understand the difference between local function calls and network requests that cost money. Every time your application makes a decision without considering the financial implications, you’re basically writing bugs that compile successfully and fail in production. The only difference is these bugs show up on your credit card statement instead of your error logs.

Illustration for Why Your Cloud Bill Is a Code Smell (And How to Fix It Without Breaking Everything)

Three Things I’ve Learned About Cloud Economics

After fifteen years of watching perfectly good architectures turn into budget black holes, I’ve learned three things. First: anything that runs constantly should be questioned aggressively. That background job that seemed reasonable when you had ten users becomes a financial disaster when you have ten thousand. Second: data movement is where clouds make their money, so treat network calls like they cost what they actually cost. Third: the default configurations are designed to maximize AWS revenue, not minimize your budget.

That last point really matters. EC2 instances default to running 24/7 because Amazon makes more money that way. Auto-scaling groups default to keeping instances warm because cold starts are annoying. RDS defaults to running continuously because databases feel like they should always be available. These defaults aren’t wrong, they’re just optimized for someone else’s bottom line.

Smart cloud cost optimization starts with recognizing that every service has an economic model designed to extract maximum value from lazy engineering decisions. The solution isn’t to fight this but to understand it well enough to make intentional choices. When you provision a t3.large instance to run a service that gets traffic for four hours a day, you’re not solving a technical problem. You’re making a financial decision that will compound for months.

Reserved Instances Are a Futures Contract, Not a Discount

The biggest cost optimization mistake I see experienced engineers make is treating reserved instances like a simple discount program. They’re not. They’re futures contracts where you’re betting on your own capacity planning skills. When you buy a three-year reserved instance, you’re telling AWS “I am confident this specific compute profile will be useful to me for the next 1,095 days.” That’s a bet even seasoned architects get wrong.

The math looks compelling: 60% off if you pay upfront for three years. But I’ve seen too many teams locked into configurations that became obsolete six months later when they migrated to containers, or switched to ARM instances, or realized their application was actually I/O bound and needed a completely different instance family. Reserved instances optimize for predictable workloads, but most interesting software projects are fundamentally unpredictable.

I think of reserved instances as insurance against your own success. Buy them for the base capacity you’re confident you’ll need regardless of what happens to your architecture. Everything else should run on spot instances or serverless infrastructure that scales to zero. This means doing the boring work of understanding your application’s usage patterns well enough to separate the predictable baseline from the variable spikes.

The real cost optimization happens when you design systems that can gracefully handle infrastructure being yanked out from under them. Spot instances can disappear with two minutes notice, but they’re 90% cheaper than on-demand. Building for this constraint forces you to write more resilient code, which usually ends up being better code anyway.

Monitoring Costs Like Performance Metrics

The most effective cost optimization tool I’ve implemented is treating cloud spending like any other performance metric. We set up alerts for unusual spending patterns the same way we monitor for elevated error rates or response times. A sudden spike in data transfer costs is just as actionable as a spike in memory usage, and usually more urgent since it directly impacts the business.

Cost monitoring requires the same discipline as performance monitoring. You need baseline metrics, anomaly detection, and clear escalation paths. When your S3 bill doubles overnight, someone should get paged. When your Lambda concurrency limit gets hit and starts throttling, that’s both a performance problem and a cost optimization opportunity. The systems that scale most efficiently are the ones where cost considerations are built into the architecture from day one, not tacked on later when the bills start hurting.

Here’s what I’ve realized: cost optimization and performance optimization are often the same problem viewed from different angles. Inefficient code that makes too many database calls doesn’t just slow down your application, it also drives up your RDS costs. A poorly designed caching strategy doesn’t just impact user experience, it also results in unnecessary compute and data transfer charges. When you fix performance problems properly, the cost improvements usually follow automatically.

I’ve started including cost-per-transaction metrics in our standard application dashboards, right next to response times and error rates. It’s remarkable how differently engineers think about architectural decisions when they can see the direct financial impact of their code changes. That elegant microservices architecture looks less appealing when you realize it’s generating thousands of cross-service calls that each cost money.

The Automation Paradox

Here’s something counterintuitive: the more you automate your infrastructure, the easier it becomes to waste money at scale. Automation is supposed to save costs by eliminating human error, but it also eliminates human judgment. I’ve seen Terraform configurations that spin up identical staging environments for every pull request, each one costing $200 per day and getting forgotten for weeks.

The solution isn’t less automation but smarter automation that understands economics. Your CI/CD pipeline should automatically tear down resources when they’re not needed. Your auto-scaling groups should have aggressive scale-down policies. Your monitoring should automatically identify idle resources and either shut them down or flag them for manual review. Good automation doesn’t just create infrastructure, it also destroys it when appropriate.

This requires shifting from thinking about infrastructure as pets to thinking about it as cattle that costs money to feed. Every resource should justify its existence continuously, not just at provisioning time. The most cost-effective systems I’ve worked with treat resource lifecycle management as a core architectural concern, not an operational afterthought.

What’s your worst cloud bill horror story? I’m always curious to hear about creative ways people have accidentally optimized for AWS shareholder value instead of their own. The best cost optimization strategies usually emerge from understanding exactly how things went wrong in the first place.

The API Design Patterns That Actually Matter (And the Ones That Don’t)

When Your API Becomes Someone Else’s Monday Morning Problem

Last month, I watched a junior developer spend four hours trying to figure out why our pagination endpoint was returning inconsistent results. The issue wasn’t in their code—it was in our API design. We had mixed cursor-based pagination with offset-based pagination across different endpoints, created three different error response formats, and somehow convinced ourselves this was “flexible.” The developer’s frustration was justified. Our API had become the digital equivalent of furniture assembly instructions written by committee.

Good API design isn’t about following every pattern in the book. It’s about choosing patterns that reduce cognitive load for developers who will inevitably be debugging your decisions at inconvenient hours. After fifteen years of building APIs that range from “surprisingly delightful” to “technically functional but emotionally devastating,” I’ve learned which patterns actually move the needle and which ones just add complexity for the sake of appearing sophisticated.

Resource-Based URLs: The Foundation That Actually Holds

RESTful resource naming isn’t just academic theory. It’s the difference between an API that feels intuitive and one that requires a decoder ring. The pattern is deceptively simple: use nouns for resources, HTTP verbs for actions. GET /users/123/orders tells a story. GET /getUserOrders?userId=123 makes developers guess whether you also have getOrderUsers somewhere.

But here’s where most teams stumble: nested resources. I never nest more than two levels deep. GET /users/123/orders/456/items/789 might feel logically pure, but it creates brittle URLs that break when business logic changes. Instead, GET /order-items/789 with proper filtering parameters gives you the same data with URLs that won’t shatter when you realize orders can have multiple users.

The real test comes when you need to handle actions that don’t fit the resource model. Instead of forcing everything into REST’s constraints, be pragmatic. POST /orders/123/cancel is clearer than trying to shoehorn cancellation into a PATCH operation. Your API should feel like a well-organized toolbox, not a philosophical statement about HTTP semantics.

Error Responses: Your API’s Emotional Intelligence

Error handling separates APIs that developers tolerate from APIs they actually enjoy using. The difference lies in providing context, not just status codes. A 400 response that says “Bad Request” is about as helpful as a GPS that says “You’re going the wrong way” without mentioning which turn you missed.

I use a consistent error response structure across my entire API. Every error response includes a machine-readable error code, a human-readable message, and when applicable, field-specific validation errors. For example, when a user submits an invalid email during registration, return a 400 with {"error": "VALIDATION_FAILED", "message": "Please check the highlighted fields", "fields": {"email": "Must be a valid email address"}}. The error code helps developers handle specific cases programmatically, while the message and field details help them build better user experiences.

Don’t underestimate the power of helpful error messages in development environments. Include request IDs for traceability, suggest alternatives when endpoints are deprecated, and provide links to documentation when possible. A developer who receives a clear error message at 2 AM will remember your API fondly. One who gets cryptic responses will remember it differently.

Pagination: Where Performance Meets Reality

Every API eventually faces the pagination question, usually right after someone tries to load a million records and brings down your database. The choice between offset-based and cursor-based pagination isn’t academic. It determines whether your API scales gracefully or becomes progressively slower as datasets grow.

Offset-based pagination (?page=5&limit=20) feels intuitive because it maps to human expectations about pages. But offset queries become expensive on large datasets because the database has to count and skip records. Cursor-based pagination (?after=eyJpZCI6MTIzfQ&limit=20) performs consistently regardless of dataset size, but makes it impossible to jump to arbitrary pages.

Choose based on your use case. If users need to jump to specific pages or need total counts for progress indicators, accept the performance trade-off of offset pagination but implement reasonable limits. If you’re building feeds or infinite scroll interfaces, cursor pagination is your friend. Facebook’s Graph API uses cursor pagination for feeds but provides offset pagination for admin interfaces. Context matters more than consistency.

Rate Limiting: The Polite Bouncer Pattern

Rate limiting is like having a good bouncer at a club. It protects the venue while being clear about the rules. Implement rate limiting early, even if your current traffic doesn’t require it. The patterns you establish under low load determine how gracefully your API handles growth.

Use standard headers to communicate limits: X-RateLimit-Remaining, X-RateLimit-Reset, and Retry-After in 429 responses. These aren’t just nice-to-haves. They enable client-side libraries to implement intelligent backoff strategies. Without them, developers resort to guessing, which usually means either being overly aggressive or overly cautious with retry logic.

Consider different limits for different types of operations. Reading data might allow 1000 requests per hour, while operations that send emails might be limited to 10 per hour. Document these limits clearly and provide different tiers if possible. Shopify’s API does this well. They provide detailed rate limiting information and even offer webhook endpoints to reduce the need for polling, which naturally reduces rate limit pressure.

The Patterns That Actually Stick

The best API design patterns are the ones that become invisible to developers using them. They reduce decision fatigue, provide clear mental models, and fail gracefully when things go wrong. Focus on consistency within your API before worrying about conforming to every REST principle or GraphQL best practice.

Your API is ultimately a conversation between your system and the developers who build on it. Make that conversation as clear and pleasant as possible. What patterns have saved you the most debugging time? What design decisions do you wish you could revisit with the wisdom you have now?

Why Your Distributed System Debugging Strategy Is Probably Wrong (And What Actually Works)

The Mythology of Distributed Debugging

After fifteen years of being summoned to war rooms at ungodly hours, I’ve noticed something weird about how we approach debugging distributed systems. We’ve created this mythology around it being impossibly complex, requiring specialized tools that cost more than a Tesla, and demanding the sacrifice of junior developers to the observability gods. The truth is both simpler and messier than the vendor pitches suggest.

Why Your Distributed System Debugging Strategy Is Probably Wrong (And What Actually Works)

Most debugging strategies I encounter suffer from what I call “tool-first thinking.” Teams buy expensive APM solutions, instrument everything that moves, and then wonder why they’re drowning in alerts while their actual problems remain invisible. It’s like trying to find a gas leak with a thermal camera when what you really need is your nose.

The real problem isn’t that distributed systems are impossible to debug. We’re applying monolithic debugging mental models to completely different problems. When your application spans twelve microservices across three cloud regions, the old “add some print statements and see what happens” approach doesn’t just fail. It actively misleads you.

Illustration for Why Your Distributed System Debugging Strategy Is Probably Wrong (And What Actually Works)

Start With the Failure, Not the Tools

Every senior engineer has that story about the time they spent three days chasing phantom latency spikes through distributed traces, only to discover the problem was a misconfigured load balancer health check. The pattern is always the same: we start with our fancy tools instead of starting with the failure itself.

Here’s what actually works: begin every debugging session by clearly defining what “working” means for this specific request flow. Not in abstract terms, but concretely. “User clicks checkout, payment service validates the card within 200ms, inventory service reserves items, and confirmation email sends within 5 seconds.” Now you have a testable hypothesis about where things might be breaking.

The next step is to trace one complete request manually, end to end, ignoring what your dashboards are telling you. Pick a specific failing request ID and follow it through your system like a bloodhound. Check the logs. Verify the database writes. Confirm the message queue deliveries. This sounds tedious, but it’s faster than spending two days correlating metrics that point you in the wrong direction.

I’ve seen teams solve weeks-old mysteries in hours using this approach. The key insight is that distributed systems fail in very specific ways, and those failure patterns become obvious when you follow the actual data flow instead of trying to guess from aggregate metrics.

The Three-Layer Debug Strategy That Actually Scales

After debugging enough production fires, I’ve settled on a three-layer approach that scales from small incidents to those “all hands on deck” disasters that make your CEO nervous. Each layer has a different purpose and requires different tools and mindsets.

Layer one is immediate triage. Your goal here isn’t to find root cause but to stop the bleeding and gather initial evidence. Check service health, verify recent deployments, and look for obvious environmental changes. This is where your monitoring dashboards earn their keep. You’re not trying to solve the mystery yet. You’re just figuring out which services are involved and how bad things are.

Layer two is systematic investigation. This is where you break out the distributed tracing, start correlating logs across services, and begin forming hypotheses about causation versus correlation. The key principle here is to maintain a clear mental model of your system’s normal operation so you can spot deviations. If you don’t know how your system behaves when it’s healthy, you can’t effectively debug when it’s sick.

Layer three is deep forensics. Sometimes you need to go beyond your standard observability stack and start examining network captures, database query plans, or JVM garbage collection logs. This layer requires the most expertise but also gives you the most definitive answers. The trick is knowing when you need to go this deep versus when you’re just procrastinating on fixing an obvious configuration problem.

Why Context Switching Is Your Enemy

The biggest productivity killer in distributed debugging isn’t technical complexity. It’s cognitive overhead. When you’re juggling twelve browser tabs, three terminal sessions, and a Slack conversation while trying to correlate events across different time zones, your brain starts making mistakes. Simple mistakes that cost hours.

I’ve learned to be ruthlessly disciplined about maintaining debugging context. Keep a running log of what you’ve checked, what you’ve ruled out, and what you’re testing next. It sounds elementary, but when you’re three hours into a complex investigation and someone asks you what you’ve tried so far, you’ll be grateful for the notes.

More importantly, resist the urge to investigate multiple theories at once. I know it feels efficient to check the database while waiting for trace data to load while also reviewing recent commits, but it’s not. Pick one hypothesis, test it thoroughly, then move to the next. Your future self will thank you when you’re not trying to remember whether that connection pool issue was related to the deployment from Tuesday or the configuration change from Wednesday.

The most effective debuggers I know have developed almost ritualistic approaches to managing their investigation state. They use dedicated debugging environments, maintain clean workspace layouts, and have systems for tracking their progress through complex problems. It’s not about the specific tools. It’s about reducing the cognitive load so you can focus on the actual problem-solving.

Building Systems That Debug Themselves

The best debugging strategy is designing your system so that debugging becomes straightforward rather than heroic. This isn’t about adding more monitoring. It’s about building introspection into your system’s DNA from the beginning.

Start with request correlation IDs that flow through every service and appear in every log line. This sounds obvious, but you’d be amazed how many systems I encounter where tracking a request across services requires detective work. Next, implement health checks that actually test the things that break. A health endpoint that returns “OK” because the web server is running tells you nothing useful about whether your database connections are timing out.

Design your error messages for future you at 3 AM. Include enough context to understand what the system was trying to do when it failed. “Connection timeout” is not helpful. “Connection timeout after 5000ms while attempting to write order 12345 to payments database primary in us-east-1” gives you something to work with.

Finally, embrace structured logging and resist the temptation to log everything. Well-structured logs for important events beat verbose debug logs for every function call. You want to be able to reconstruct the story of what happened, not wade through novels of irrelevant details.

These principles might seem basic, but they’re the difference between debugging being an art form practiced by senior engineers in darkened rooms and being a systematic skill that any competent developer can execute. The goal isn’t to eliminate all debugging. It’s to make the inevitable problems manageable rather than mystical.

I’m curious about your own debugging war stories and whether these approaches align with what you’ve learned in the trenches. What’s the strangest distributed system bug you’ve encountered, and how did your debugging strategy need to change to catch it?

The Boring Truth About Microservices: When Conway’s Law Beats the Hype Machine

The Database That Started Everything

Three years ago, I watched a perfectly competent engineering team spend eighteen months migrating their monolith to microservices, only to discover they’d recreated the same bottleneck in six different places. The culprit wasn’t architecture philosophy or deployment complexity. It was a single PostgreSQL instance that every service still hammered for user data, now with extra network hops and JSON serialization overhead.

The Boring Truth About Microservices: When Conway's Law Beats the Hype Machine
The Boring Truth About Microservices: When Conway’s Law Beats the Hype Machine

This is the conversation nobody wants to have at architecture reviews. We debate service boundaries and API contracts while ignoring the elephant in the room: most microservices migrations fail not because of technical decisions, but because teams underestimate the organizational changes required. Conway’s Law doesn’t just apply to code structure. It applies to how your database schemas evolve, how your incident response works, and whether your junior developers can actually understand what’s happening when things break.

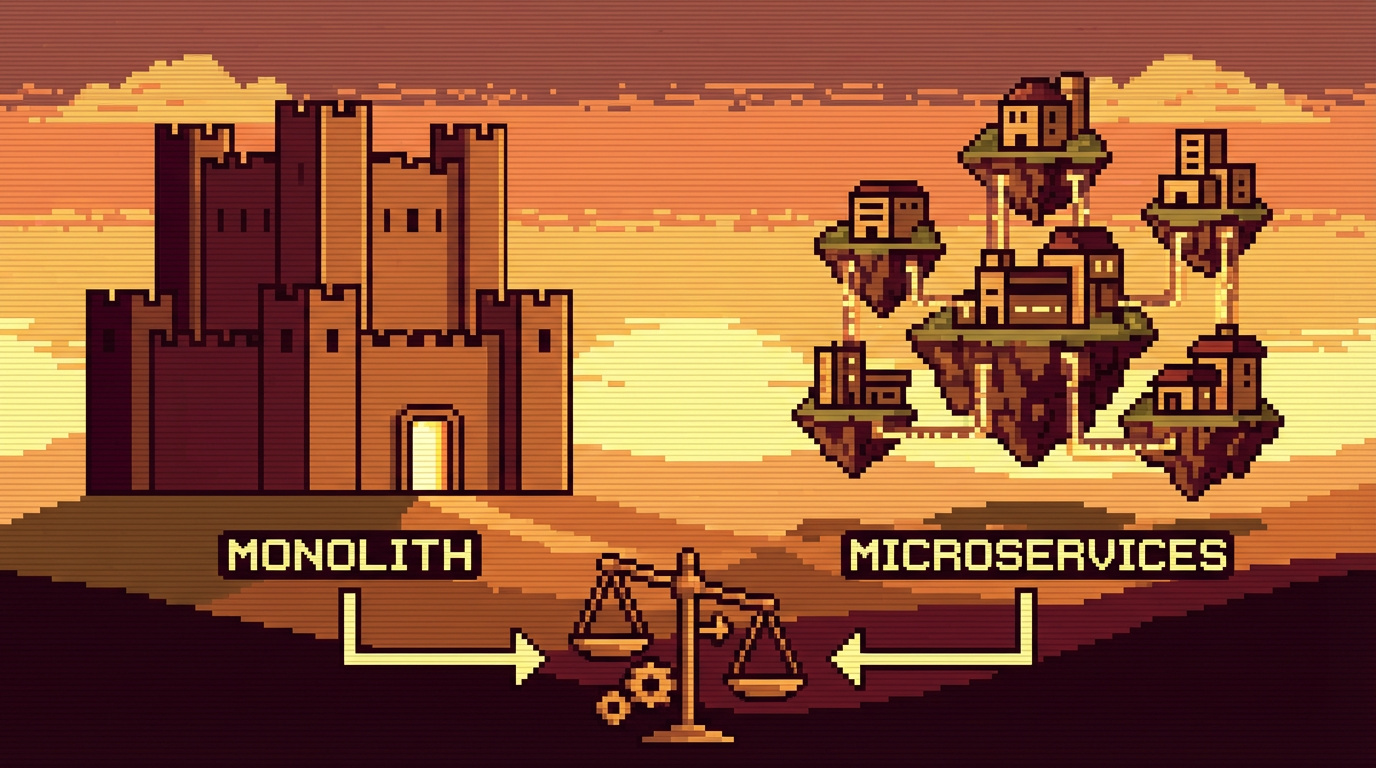
The real trade-off isn’t between microservices and monoliths. It’s between complexity you can see and complexity you can’t. Monoliths hide their complexity in tight coupling and shared state. Microservices hide theirs in network calls and distributed transactions. Neither is better by default, but one might be better for your team right now.

Illustration for The Boring Truth About Microservices: When Conway's Law Beats the Hype Machine
Illustration for The Boring Truth About Microservices: When Conway’s Law Beats the Hype Machine

The Operational Reality Check

Here’s what the conference talks don’t tell you about running microservices in production. Your monitoring bill will triple before you figure out distributed tracing. Your deployment pipeline will break in fascinating new ways when service A depends on service B, but service B’s tests require service C to be running, and service C just got refactored by a team in another timezone.

I’ve seen teams ship features faster with a well-structured monolith than with a dozen microservices managed by Kubernetes. The monolith team could grep their codebase, run their tests locally, and deploy with confidence. The microservices team spent more time updating Helm charts than writing business logic. Sure, your experience might be different, but the operational overhead is real and it scales with the square of your service count.

The part nobody talks about is debugging at 3 AM. When something breaks, you want stack traces, not service mesh timeout logs. You want to step through code in a debugger, not piece together a transaction from fourteen different log aggregation queries. The cognitive load of distributed debugging isn’t trivial, and you can’t easily train it away.

The Conway’s Law Accelerator

The most compelling reason I’ve seen for microservices has nothing to do with scalability or fault isolation. It’s an organizational forcing function. When done right, microservices make team boundaries explicit and prevent the slow organizational entropy that turns clean codebases into unmaintainable messes.

A team that owns a service is responsible for its entire lifecycle. They can’t blame another team’s code for their performance problems. They can’t casually add dependencies on internal APIs without considering the maintenance burden. They have to think about backwards compatibility, monitoring, and failure modes in ways that shared codebases often discourage.

This is why the most successful microservices adoptions I’ve seen happened at companies with strong engineering culture and clear team ownership models. The teams that struggled were usually dealing with unclear responsibilities, shared on-call rotations, or matrix management structures. No amount of Docker containers can fix organizational dysfunction, but they can certainly make it more expensive.

The Pragmatic Path Forward

The boring truth is that most applications should start as modular monoliths and stay that way longer than their architects want to admit. Extract services when you have clear team boundaries, well-defined interfaces, and genuine operational need for independent scaling or deployment. Don’t extract services because you read a blog post about Netflix’s architecture.

The best migration strategy I’ve seen treats microservices as an organizational optimization, not a technical one. Start by identifying natural team boundaries in your product. Build strong internal APIs within your monolith. Invest in observability and deployment automation before you need them. Then, when you do extract a service, you’re optimizing for team autonomy rather than fighting framework limitations.

The companies that get this right don’t have religious debates about architecture. They have pragmatic conversations about team structure, ownership models, and operational maturity. They measure migration success by delivery velocity and incident response time, not by service count or container density.

What’s your experience been with the monolith-to-microservices journey? I’m particularly curious about the organizational changes that made the biggest difference in your migrations, or the subtle operational issues that caught your team off guard.

The Great Microservices Migration: What They Don’t Tell You in the Conference Talks

When the Monolith Became the Enemy

Three years ago, our engineering team sat in a conference room staring at a sprawling monolith that had grown from a scrappy startup MVP into something resembling a digital Frankenstein’s monster. The application handled everything from user authentication to payment processing to inventory management, all wrapped in a single deployable unit that took forty-seven minutes to build and required a PhD in archaeology to understand the dependency graph. The decision to break it apart into microservices felt inevitable, even righteous.

The Great Microservices Migration: What They Don't Tell You in the Conference Talks
The Great Microservices Migration: What They Don’t Tell You in the Conference Talks

Looking back, that feeling of inevitability should have been our first red flag. We were caught up in the same evangelical fervor that sweeps through engineering teams when a new architectural pattern promises to solve all our problems. The conference talks made it sound so clean: small, focused services that could be developed, deployed, and scaled independently. Teams could move faster, technology choices could be more flexible, and surely our production incidents would become a thing of the past.

The reality, as it turns out, was much messier than the slide decks suggested.

Illustration for The Great Microservices Migration: What They Don't Tell You in the Conference Talks
Illustration for The Great Microservices Migration: What They Don’t Tell You in the Conference Talks

The Migration Reality Check

The first service we extracted was user authentication, which seemed like a logical starting point. Simple domain, well-defined boundaries, and relatively few dependencies. What could go wrong? Everything, as it turned out, but in ways that were both predictable and completely unexpected.

The predictable problems were around distributed systems complexity. Network calls that used to be in-memory method invocations suddenly had latency, timeouts, and retry logic to consider. Our previously atomic operations became eventually consistent distributed transactions with all the joy that entails. Testing became an exercise in choreographing multiple services, and local development required running a constellation of dependencies that consumed more RAM than our laptops possessed.

The unexpected problems were more insidious. Our carefully crafted service boundaries turned out to be more like suggestions than actual walls. The authentication service needed user profile data for JWT claims, which meant either duplicating data or making the profile service a dependency. Both choices felt wrong, but we had to ship something. We chose duplication and told ourselves we’d fix it later, a decision that still haunts our data consistency models to this day.

Six months into the migration, we had successfully transformed one medium-sized problem into twelve smaller problems that somehow felt larger in aggregate. The team was spending more time on infrastructure and inter-service communication than on actual business logic. Our deployment pipeline had evolved into a complex orchestration of service dependencies that made the original monolith build look quaint by comparison.

The Unexpected Benefits and Genuine Trade-offs

Here’s where it gets interesting though. Around month eight, something clicked. The teams responsible for individual services started developing a deeper understanding of their domains. The authentication team became genuine experts in OAuth flows and token management. The payment team dove deep into PCI compliance and fraud detection. Specialization bred expertise in ways that the monolith had never encouraged.

More importantly, we discovered that some services genuinely needed to scale differently. Our image processing service required completely different infrastructure than our user management service. The monolith had forced us into a one-size-fits-all approach that was suboptimal for everyone. Being able to choose the right tool for each job turned out to be more valuable than we’d anticipated, even if it did mean learning Rust, Go, and keeping our existing Python services running simultaneously.

The real revelation came during our first major incident post-migration. When the payment service went down, users could still browse products, manage their profiles, and even add items to their carts. The blast radius was contained in a way that would have been impossible with the monolith. Yes, we had more moving pieces to monitor and debug, but when things went sideways, they went sideways in predictable, isolated ways.

What Actually Matters in the Decision

After living through both sides of this architectural divide, I’ve concluded that the microservices versus monolith debate often focuses on the wrong variables. The question isn’t whether microservices are inherently better or worse than monoliths. The question is whether your team and organization are equipped to handle the operational complexity that comes with distributed systems.

If you have a team of five engineers who are already struggling to maintain consistent coding standards and deployment practices, adding network boundaries and service coordination to the mix will not improve your situation. Microservices amplify both your capabilities and your dysfunction. A team that can’t manage database migrations reliably will not suddenly become competent at managing distributed transactions and eventual consistency.

The organizational factors matter more than the technical ones. Do you have dedicated devops expertise? Can your monitoring and observability stack handle distributed tracing across multiple services? Are your teams mature enough to own services end-to-end, including on-call responsibilities? These aren’t glamorous questions, but they’re the ones that determine whether your microservices migration becomes a productivity multiplier or a cautionary tale.

The Wisdom of Boring Choices

Two years post-migration, our architecture is a hybrid that would make purists on both sides uncomfortable. Some services remained as part of a smaller but still substantial monolithic core. Others were extracted successfully and operate as independent services. A few were merged back together when the service boundaries proved to be fundamentally wrong.

The most successful extractions were the ones driven by genuine operational needs rather than architectural ideology. The image processing service needed different scaling characteristics and made sense as a separate deployment. The notification service needed to integrate with multiple third-party APIs and benefited from isolation. The user profile service, despite being a seemingly obvious candidate for extraction, worked better when it remained part of the core monolith because of its tight coupling with authentication and authorization logic.

This middle path lacks the elegance of a pure microservices architecture or the simplicity of a well-designed monolith. But it reflects the messy reality of working with software systems that have real constraints and real deadlines. Sometimes the most innovative choice is the boring one that acknowledges your current capabilities rather than your aspirational ones.

The conference talks rarely mention that the most successful architectural decisions are often the ones that feel slightly disappointing at the time. They’re based on honest assessments of team capabilities, operational maturity, and business requirements rather than the latest trends or the most intellectually satisfying patterns. If you’re wrestling with this decision for your own systems, I’d love to hear about your specific constraints and trade-offs. The devil, as always, is in the details that don’t make it into the blog posts.

Frontend Framework Architecture: A Career Survival Guide to React, Vue, and Angular

Why Framework Architecture Matters More Than You Think

After fifteen years of watching developers chase the latest shiny framework only to find themselves maintaining a legacy Angular 1.x app that nobody wants to touch, I’ve learned something important: the architecture of your chosen frontend framework will define your next five years. Not the syntax sugar, not the GitHub stars, not even the bundle size. The underlying architectural decisions that the framework authors made will become your daily reality.

Frontend Framework Architecture: A Career Survival Guide to React, Vue, and Angular

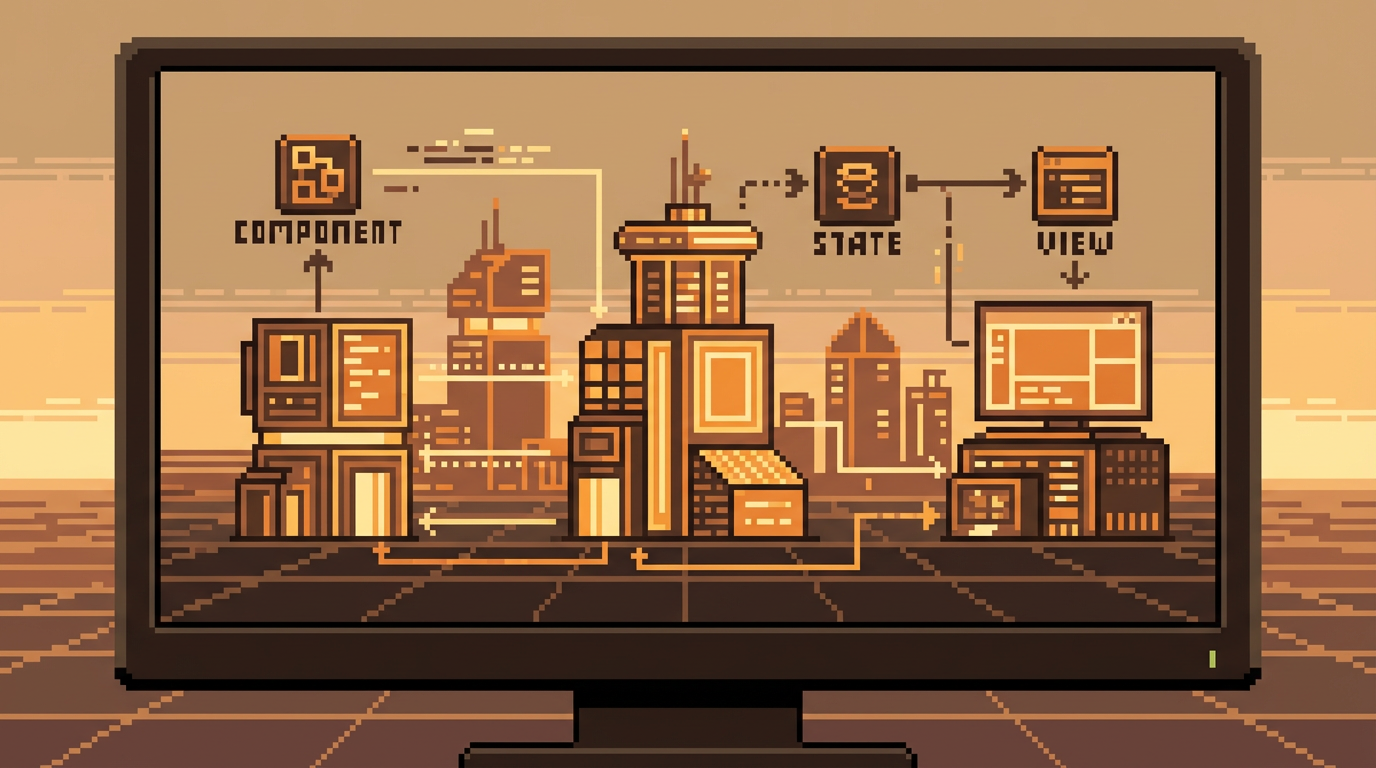
When I started my career, jQuery ruled the world and we thought we were sophisticated for using plugins. Today’s frontend world is completely different. React’s component-based architecture taught an entire generation to think in terms of unidirectional data flow. Vue’s template-driven approach made reactive programming accessible to developers coming from traditional server-side backgrounds. Angular’s opinionated structure gave enterprise teams the guardrails they desperately needed.

Each of these architectural approaches shapes how you solve problems, how you structure teams, and ultimately, how marketable your skills remain. Understanding these differences isn’t an academic exercise. It’s career insurance.

Illustration for Frontend Framework Architecture: A Career Survival Guide to React, Vue, and Angular

React’s Component Composition: The Unix Philosophy for UIs

React’s genius lies in its architectural restraint. By focusing exclusively on the view layer and embracing functional composition, React forces you to make explicit decisions about state management, routing, and data fetching. This might seem like extra work, but it’s actually a career multiplier. When you understand how to compose complex UIs from simple, predictable components, you’re learning a transferable skill that extends far beyond React itself.

The virtual DOM isn’t just an implementation detail. It’s a mental model that separates what you want to happen from how it happens. This abstraction has proven so powerful that other frameworks have adopted similar approaches. Once you internalize this pattern, you start seeing opportunities for composition everywhere. Database queries become composable functions. API responses become predictable state transitions.

React’s ecosystem reflects this compositional philosophy. You’ll spend time learning Redux or Zustand for state management, React Router for navigation, and probably a dozen other libraries to build a complete application. Critics call this “JavaScript fatigue,” but I call it “JavaScript fluency.” Each library you integrate deepens your understanding of how modern web applications actually work. This knowledge compounds over your career in ways that framework-specific conventions never will.

The career implication here is huge. React developers become system thinkers. They learn to evaluate trade-offs, understand performance characteristics, and build mental models for complex state interactions. These skills translate directly to backend development, mobile development, and system design interviews at senior levels.

Vue’s Progressive Enhancement: The Pragmatist’s Framework

Vue’s architecture embodies a different philosophy: gradual complexity. You can sprinkle Vue components into an existing jQuery application, or build a full single-page application with the same framework. This flexibility isn’t accidental. It’s an architectural decision that reflects how real software development actually works in most organizations.

Vue’s template syntax feels familiar to anyone who’s worked with server-side templating engines. The reactive data binding happens behind the scenes, using ES5 getters and setters under the hood in Vue 2, and Proxies in Vue 3. This abstraction means you write less boilerplate code, but it also means you need to understand Vue’s reactivity system when things go wrong. And things always go wrong.

The component-based architecture shares DNA with React, but Vue’s single-file components create a different development experience. CSS, HTML, and JavaScript live together in one file, which feels natural for component-scoped styles but can become messy for complex components. The tooling around Vue has matured significantly, with Vite providing an exceptional development experience and TypeScript integration that rivals React’s ecosystem.

From a career perspective, Vue occupies an interesting middle ground. It’s less ubiquitous than React but more approachable than Angular. Vue developers often become the bridge between design and engineering teams because the framework’s template-driven approach maps closely to how designers think about component libraries. If you enjoy working closely with design systems and care about developer experience, Vue’s architecture aligns well with these priorities.

Angular’s Opinionated Structure: Enterprise Architecture as a Feature

Angular isn’t just a framework. It’s a platform. The distinction matters because Angular’s architecture makes specific assumptions about how you want to build applications. Dependency injection, decorators, observables, and TypeScript aren’t optional features you can adopt gradually. They’re fundamental to how Angular applications work. This opinionated approach has trade-offs that directly impact your career trajectory.

The dependency injection system teaches you to think about application architecture in terms of services, modules, and hierarchical injectors. These concepts translate directly to backend development patterns, particularly if you’re working with Spring, .NET, or other enterprise frameworks. Angular developers often become full-stack developers more easily because the architectural patterns feel familiar across the technology stack.

Angular’s commitment to TypeScript from day one has aged remarkably well. While React and Vue have added TypeScript support, Angular developers have been thinking in types for years. This early exposure to static typing often makes Angular developers more effective when working with typed languages, GraphQL schemas, or API design. The tooling ecosystem reflects this maturity, with Angular CLI providing scaffolding, testing, and build optimization that rivals mature backend frameworks.

The career implications here skew toward enterprise development and larger teams. Angular’s architectural guardrails prevent many common mistakes but require more upfront investment to master. If you’re targeting senior roles at larger companies or considering a transition to backend development, Angular’s structured approach provides valuable experience with software engineering patterns that extend beyond frontend development.

The Meta-Skill: Choosing the Right Tool for the Right Job

The most valuable skill isn’t mastering one framework’s architecture. It’s developing the judgment to match framework characteristics to project requirements and team dynamics. React’s flexibility shines when you need to integrate with existing systems or when your team includes experienced JavaScript developers who can navigate the ecosystem. Vue’s gradual approach makes it ideal for teams transitioning from traditional server-side development or when you need to incrementally modernize a legacy application. Angular’s structure provides safety for large teams working on complex, long-lived applications.

Understanding these architectural trade-offs positions you as the developer who can have intelligent conversations about technology choices rather than defending religious preferences. This perspective becomes increasingly valuable as you progress to senior roles where technical leadership involves guiding architectural decisions rather than implementing them.

Your framework choice today shapes the problems you’ll be solving three years from now. Choose based on the career trajectory you want, not just the project you’re building right now. The architecture patterns you internalize become the lens through which you approach every subsequent technical challenge.

What architectural patterns have shaped your approach to problem-solving? I’m curious about the specific moments when framework architecture either saved you from a difficult refactor or led you into an unexpected complexity trap.

The Database Performance Optimization Hill I’m Willing to Die On

Indexing Is Not Magic Fairy Dust

After watching countless developers sprinkle indexes on database tables like they’re seasoning a poorly cooked meal, I feel compelled to state the obvious: indexes are not a universal performance panacea. They’re precise instruments that require surgical application, not blunt weapons you wield against slow queries with reckless abandon.

The Database Performance Optimization Hill I'm Willing to Die On
The Database Performance Optimization Hill I’m Willing to Die On

Here’s what drives me crazy: indexes trade write performance for read performance. They eat up storage space. They create maintenance overhead that follows you everywhere. Every single index you add is a promise to the database engine that you’ll keep it updated with every INSERT, UPDATE, and DELETE operation. When I see a table with twelve indexes handling a workload that’s 80% writes, I know I’m looking at someone who learned about indexes from a Stack Overflow answer and never bothered to understand what’s actually happening under the hood.

Composite indexes are where most people’s understanding completely falls apart. Column order matters tremendously. If you don’t get why, you’re probably creating indexes that the query optimizer will completely ignore. A composite index on (user_id, created_at, status) is absolutely not the same as an index on (status, created_at, user_id). The difference can mean sub-millisecond lookups versus full table scans that make your users question their life choices.

Illustration for The Database Performance Optimization Hill I'm Willing to Die On
Illustration for The Database Performance Optimization Hill I’m Willing to Die On

Query Patterns Matter More Than Individual Query Performance

Here’s where most database optimization efforts go completely sideways: developers obsess over making individual queries faster while totally ignoring how their application actually talks to the database. You can have perfectly optimized queries that still bring your database to its knees if you’re executing them in pathologically stupid patterns.

The classic example is the N+1 query problem. Developers write what looks like clean, obvious code that fetches a list of users and then makes a separate query to get each user’s profile information. Twenty users means twenty-one database round trips. Scale that to realistic data volumes and you’ve created a performance nightmare that no amount of individual query optimization can solve. The solution isn’t faster queries. It’s fewer queries.

Connection pooling falls into this same category. I’ve seen applications with beautifully optimized queries that still perform terribly because they’re creating and destroying database connections like disposable coffee cups. Your database server has finite resources for handling connections. If you’re not pooling them intelligently, you’re wasting cycles on connection establishment overhead that could be spent doing actual work.

Batch operations represent another fundamental shift in thinking that can dwarf the impact of micro-optimizations. Execute one INSERT statement with 1000 rows instead of 1000 individual INSERT statements. Instead of updating records one at a time in a loop, identify the pattern and write a single UPDATE with a proper WHERE clause. These aren’t just performance improvements. They’re architectural improvements that show you understand how databases actually work.

Hardware Limitations Are Your North Star

Database performance is ultimately constrained by physics. No amount of clever SQL can overcome fundamental hardware limitations. Understanding these constraints is essential for making informed optimization decisions rather than randomly trying techniques you read about in blog posts written by people who may have never managed a production database.

Storage I/O is usually your primary bottleneck, especially if you’re still running on traditional hard drives. Rotational latency is a hard physical limit. Seeking to random locations on disk takes time measured in milliseconds, which is an eternity in computer terms. This is why sequential access patterns perform dramatically better than random access patterns, and why techniques like proper clustering of related data can have enormous performance implications.

Memory hierarchy matters enormously for database performance. Data in CPU cache is orders of magnitude faster to access than data in RAM, which is orders of magnitude faster than data on SSD, which is orders of magnitude faster than data on spinning disk. Query patterns that keep frequently accessed data in higher levels of this hierarchy will consistently outperform patterns that force constant trips to slower storage layers.

Network latency becomes relevant when your application and database live in different places. A query that makes ten round trips to a database on the same local network might be imperceptibly fast. Execute that same query pattern against a database in another geographic region and suddenly you’re looking at hundreds of milliseconds of latency that no amount of query optimization can eliminate.

Monitoring Beats Guessing Every Time

The most damaging myth in database performance optimization is that experienced developers can intuitively identify performance problems. This is completely false. Human intuition is terrible at predicting where databases spend their time. The only reliable way to optimize database performance is to measure it systematically and continuously.

Query execution plans are your most powerful diagnostic tool, but only if you actually know how to read them. Most developers look at execution plans like they’re reading hieroglyphics. They focus on the wrong metrics and miss the critical information about where queries are actually spending their time. Learn to identify table scans, understand join algorithms, and recognize when the optimizer is making poor decisions about execution strategy.

Database slow query logs should be treated as production monitoring data, not debugging information you only look at when things are already broken. Set your slow query threshold aggressively low and review the logs regularly. Queries that run acceptably fast on your development database with sample data can become performance disasters when they encounter production data volumes and concurrent user loads.

Application-level monitoring provides context that database-level monitoring cannot. Response time percentiles, error rates, and throughput metrics from your application layer tell you whether your database optimizations are actually improving user experience or just making synthetic benchmarks look better.

Context Trumps Best Practices

Every database optimization technique has appropriate use cases and situations where it will make things worse. The “best practices” that work for high-volume transactional workloads may be counterproductive for analytical workloads. The optimization strategies that make sense for read-heavy applications can be disastrous for write-heavy applications. Understanding your specific context is more valuable than memorizing generic optimization checklists.

Denormalization is a perfect example of this principle. Database normalization is taught as gospel in computer science courses, and for good reason. But real-world performance requirements sometimes demand strategic denormalization. Storing calculated values, duplicating frequently accessed data, and maintaining redundant indexes can all be correct decisions in the right context, even though they violate theoretical purity.

The only universal truth in database performance optimization is that measurement and understanding your specific workload characteristics matter more than applying generic techniques. If you’re optimizing based on assumptions rather than data, you’re probably making things worse.

What’s your most controversial database optimization opinion? I’d be curious to hear about techniques that have worked well in your specific context, especially if they contradict conventional wisdom.